Tech/AI모비인사이드
OpenAI DevDay 2026 Recap — ChatGPT Becomes a Shared Workspace for People and Agents
OpenAI DevDay 2026 introduced the always-on agent Dots, GPT-6.1 Sol and ChatGPT Spaces. A recap of the shift from model races to work platforms.
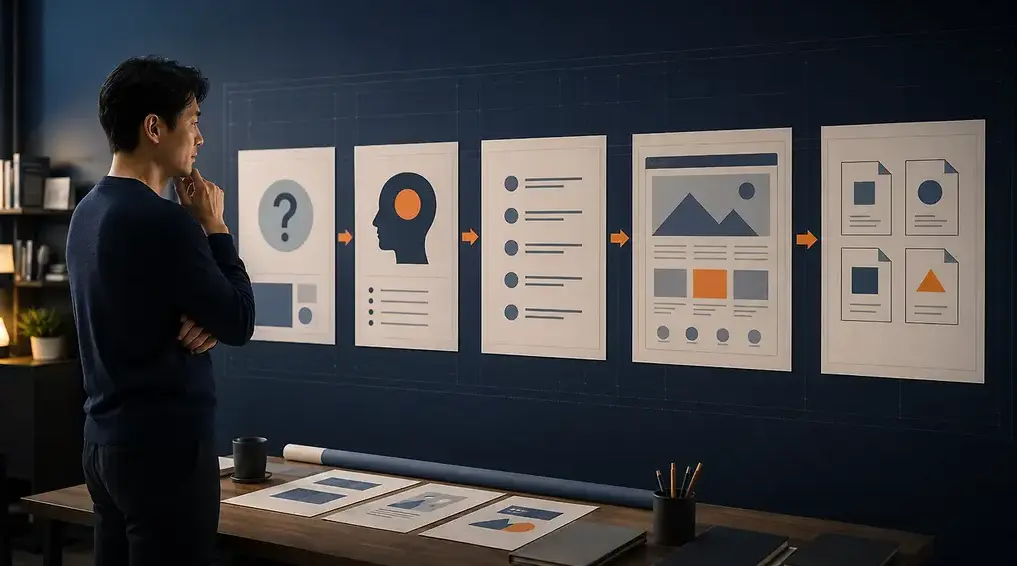
Writing with AI produces a recognizable failure. There was plenty of material and plenty to say in each chapter. Then reading the manuscript straight through, part one and part four were saying the same thing. Parts two and three encroached on each other's jobs. The sentences differed; the message the reader received overlapped.
The first instinct is to assume the content is thin — add examples, add explanation, ask the AI to rewrite it differently. The manuscript got longer without getting sharper.
The problem was not the material. It was never designing how the central message divides across parts.
The same failure repeats in website builds and automation projects. AI raises execution speed, but without structure it simply accumulates overlapping output faster.
Different parts of a book must do different jobs. In the early manuscript, "judgment criteria matter" appeared in nearly every part:
All true. But when every chapter says the same thing, the book stops moving forward. Instead of gaining a new perspective, the reader re-reads what they already heard in different words.
This is also why AI drafts keep needing rewrites. Not because the sentences are weak, but because the role each paragraph and chapter should carry was never made explicit.
Reorganized, the structure looks like this:
Once divided, the repetition becomes visible. One chapter was supposed to explain a problem but reached forward into solutions; another was supposed to show application but restarted from first principles.
If the first part fully explained why work doesn't finish even with AI, the next part must not repeat it. The next part must show what judgment hides inside expert experience.
Divided this way, the reader follows one message moving from problem to principle, principle to method, method to result rather than hearing the same message repeatedly.
The useful criterion here is MECE: mutually exclusive, collectively exhaustive — no overlap, and nothing missing when combined.
In plain terms:
A good structure is not one that packs in more content. It is one that avoids repetition and moves naturally to the next thing.
Structure must exist before you ask AI to write. "Write an article about X" produces a good collection of relevant statements. But which part is introduction, which is the core explanation, and what should remain at the conclusion is unknowable to the model.
So before prompting, settle four questions per chapter or part:
These are not techniques for writing longer prompts. They are design decisions that reduce how much you rewrite — in articles, books, websites, and proposals.
The conclusion from this process is simple. Asking "why should this part exist?" is far more effective than "let's make this sentence better."
Rewriting whenever a sentence displeases you means the same problem reappears in the next chapter. Recording the reason for the edit, by contrast, creates the criterion for the next decision:
As those criteria accumulate, AI writes better too — not because it generates more, but because a person can now tell it what to keep and what to cut.
Speed without structure accumulates overlapping sentences and similar outputs faster.
This is why website work should settle customer, problem, reasons for choosing, and inquiry flow before screens. Without dividing which question each page answers, the homepage, service page, and about page all end up saying similar things.
The same diagnosis connects to verification. Making "done" provable follows the identical structure described in why verification is the missing step in vibe coding. A paragraph whose role overlaps another has no information gain by definition.
Digital design capability is not the ability to hand AI more work. It is the ability, before handing over the work, to set criteria and direction, assign each output its role, and record the reason for each edit as the next criterion.
AI will not build that structure for you. But when the structure exists, it can execute human judgment far faster.
Not because the sentences are weak, but because the role each paragraph and chapter should carry was never defined. When roles overlap, different sentences still deliver a repeated message.
Each part answers its own question, no part re-explains at length what another already answered, and reading the whole carries the reader from problem to application without gaps.
Four things per chapter: the single message the reader takes, how it differs from the previous piece, what it will not cover, and what next question the reader should hold.
Rewriting sentences alone means the same problem recurs in the next chapter. The reason becomes the criterion for the next decision, and accumulated criteria are what let you tell AI what to keep and cut.
To apply what you just read to your own site, start with a free audit of where things are now.
A strategist replies within 24 hours on business days.
OpenAI DevDay 2026 introduced the always-on agent Dots, GPT-6.1 Sol and ChatGPT Spaces. A recap of the shift from model races to work platforms.
Zero-click GEO explained from TBWA's observations: 68% of U.S. Google searches end without a click, so extend existing SEO content into AI citations.
Claude Fable 5.1 improves coding and research while cutting cache costs, reducing false safety interventions, and introducing regulatory watermarking.