Tech/AI모비인사이드
OpenAI DevDay 2026 Recap — ChatGPT Becomes a Shared Workspace for People and Agents
OpenAI DevDay 2026 introduced the always-on agent Dots, GPT-6.1 Sol and ChatGPT Spaces. A recap of the shift from model races to work platforms.
Anthropic introduced Fable 5.1 and Mythos 5.1 in September 2026. Figures cited in the source put Fable's agentic research benchmark at 52.6%, up from 24.7% for the prior model, while its coding benchmark reached 55.8%. Standard input and output prices remained unchanged, but cache reads fell from $1 to $0.25 per million tokens. That change matters most for agents that repeatedly revisit the same documents and tool context.
Anthropic also highlighted applied research examples, including protein binder design with external lab validation, higher-resolution mapping of Venus, and GPU optimization for biological models. The purpose is to move the discussion beyond benchmark scores and show where models can participate in real research workflows.
Overly broad interventions had blocked legitimate cybersecurity and biology questions in the previous generation. Fable 5.1 is designed to reduce those false interventions while still refusing harmful tasks such as operational exploit creation. It also provides clearer explanations when a task is stopped and ties research claims more closely to numbers and sources.
Prompt-injection and reward-hacking defenses become more important as agents gain access to email, files, and business systems. Availability and policy can matter as much as raw capability. The export-control risks highlighted by Claude Fable access restrictions show why companies should assess geographic access and policy stability during procurement.
Fable 5.1 adds an invisible statistical watermark to generated text and files as part of EU AI Act compliance. The signal can survive copying because it is embedded in word-choice patterns, but it may weaken in short text, heavily edited material, translations, and code. It does not encode personal or conversational information.
Mythos 5.1 relaxes more cybersecurity and life-science restrictions but is limited to approved U.S. users. Buyers should therefore compare effective access, cache-heavy workload costs, false-positive safety behavior, audit requirements, and sourcing quality—not just the top benchmark number.
Base input and output prices stayed the same, while cache-read pricing fell by 75%, benefiting workloads that repeatedly reuse context.
They share a model foundation, but Mythos relaxes more controls in sensitive domains and is restricted to approved users in the United States.
No. Short, heavily edited, translated, or code-heavy outputs may not provide enough statistical signal for reliable detection.
To apply what you just read to your own site, start with a free audit of where things are now.
A strategist replies within 24 hours on business days.
OpenAI DevDay 2026 introduced the always-on agent Dots, GPT-6.1 Sol and ChatGPT Spaces. A recap of the shift from model races to work platforms.
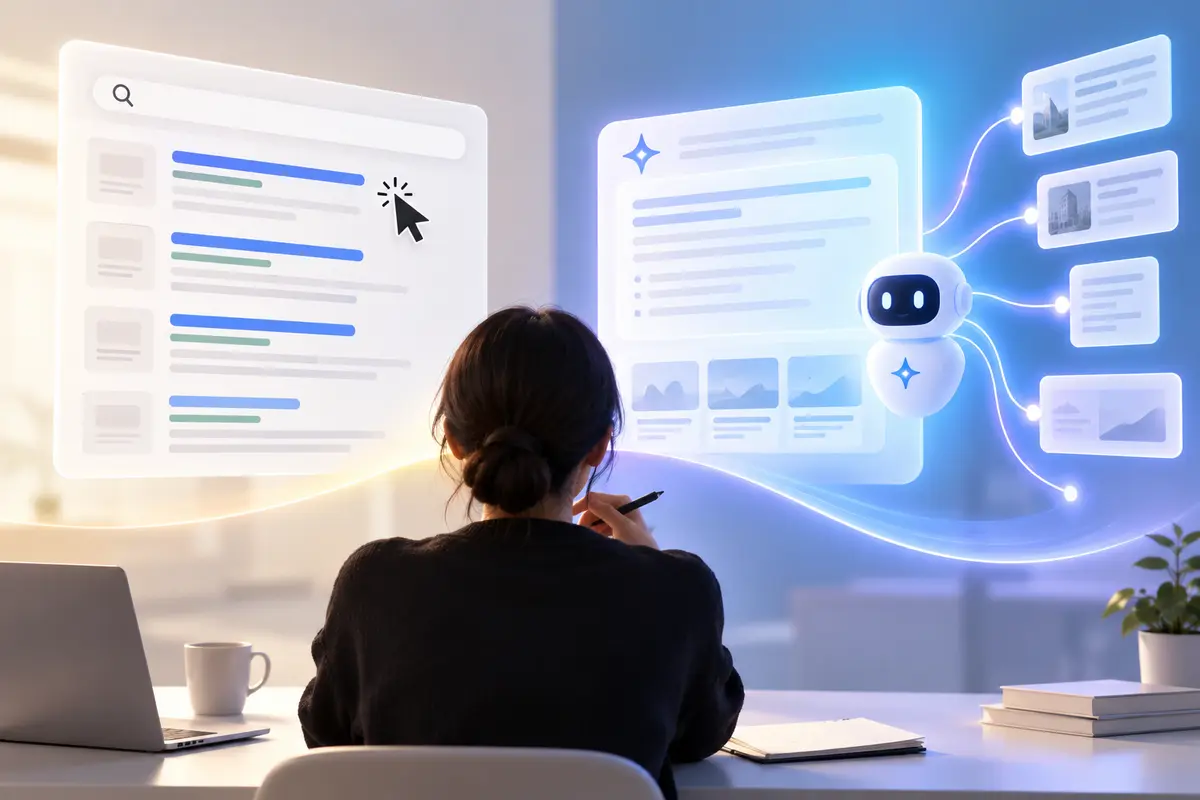
Zero-click GEO explained from TBWA's observations: 68% of U.S. Google searches end without a click, so extend existing SEO content into AI citations.
AI literacy is the ability to separate what AI can support from what humans must judge and own. The three components, practical application, and corporate training examples.